AI broke one of software’s oldest assumptions
For 40 years, software ran on one assumption: same input, same output. Determinism. It’s why a regression suite works at all. If you run the same test a thousand times, you’ll get the same result.
Code review exists for a related reason. We know that if you give two engineers the same ticket, they’ll write two different implementations. Humans are non-deterministic, so we built the code review process to catch what any one person might miss.
But with the adoption of AI-powered code generation, the part of the pipeline generating the most code isn’t deterministic either. Even when you’re using the same prompt and the same model, you’ll get a different output from one run to the next. And the failure mode isn’t garbage code. Garbage code is relatively easy to catch. You can see it, update your code, swap models, adjust your prompts, and move on.
The failure mode now is plausible code. It looks polished, even if the output is different every time you generate it with an agentic harness. It passes the eye test, which is exactly why the old guardrails don’t work any more. In the past, you could evaluate a tool once and trust the output, because the artifact stayed the same every time after the tool ran, but now the artifact moves under you. Now we have to engineer the entire software development pipeline to assume that anomalies will happen.
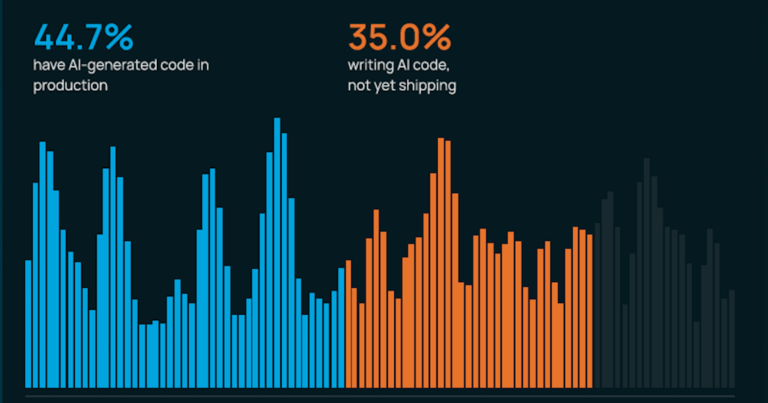
In our AI Code Generation Reality Check webinar, where we broke down our survey of engineering leaders, I told a story that speaks to this problem directly: an internal LLM-as-judge caught a foundation model update that would have broken user-facing functionality, before it shipped. A single PR review wouldn’t have caught it.
You can’t stop a non-deterministic system from surprising you, but you can get fast at catching issues, and understanding how big the blast radius of an incident may be. Detection needs a signal you can trust. And for most orgs, the primary system that provides that visibility is no longer effective.
Ticket systems break down twice
Every platform built on ticket data has the same problem: tickets capture intent, not work. That gap gets worse as code volume increases.
Analysts covering this category have flagged the same thing. The bigger and more complex the organization, the more that gap compounds. When there are multiple business units and a couple of acquisitions in the last year, no amount of documented process will ensure that everyone is filling out tickets the same way, all the time. That’s not the way humans work.
That’s a second failure, distinct from tickets not keeping up with AI speed. Tickets also don’t hold together well across a large, changing org, with or without AI in the mix.
What the highest-performing teams are doing differently
In the webinar, we discussed three common approaches:
- Engineering leaders have moved past whether to use AI and on to where it has the most impact. Typically they start with tests and scaffolding and ensure human eyes and hands remain on core business logic the longest.
- Teams believe code review requires an ensemble of tools: linters and CI bots, AI code review, human review reserved for the highest-risk changes, and engineering intelligence to catch the trends no single PR reveals.
- They look at the whole codebase, not just the diff. A PR tells you what changed today. It doesn’t tell you what’s sitting untouched in a repo nobody’s opened in a year, accumulating risk until someone finally has a reason to go back in.
Questions from the webinar
We got more good questions than we had time to answer. Here are four of them. Please reach out if you have more questions about the webinar.
1. From my experience using AI, I have noticed that if you can master the context, then you can definitely get the AI model, no matter what model it is, to generate a good quality response. Is that true? Do you agree?
Mostly, with a catch. You’re right that context matters enormously, and for most teams it’s the highest-leverage thing they’re not doing well yet. But there are risks when you tackle larger pieces of work. For example, there tends to be a middle zone in a large context window where instructions you flagged as important stop reliably getting followed. It shows up in architectural drift, small deviations that build up over a series of changes rather than one clear break. That issue is particularly hard for a single PR review to catch. The fix isn’t more context alone, it also requires checks that assume drift will happen. We use sub-agents, verification steps, and a second pass over the code to find those types of issues. While we agree that models plus great context goes a long way, it’s not a substitute for verification.
2. Does code-first visibility actually change what you catch, or is it just a different window onto the same information?
Both. The immediate answer is pace. You see changes as they occur instead of waiting for a sprint retro to surface them. The more interesting answer is agentic root-cause analysis, and it’s something we’re actively building: flag a DORA metric moving in the wrong direction, trace it to the specific pull requests behind it, then automatically analyze why. It might be a new dependency carrying a vulnerability or complexity spiking in one part of the codebase for six months straight.
It also ties back to tickets: a lot of that evidence, rework in particular, never makes it into a ticket at all. Refactors and tech debt cleanup are the work that keeps the lights on. It’s real, it should be quantified, and the code shows it even when the ticketing system doesn’t. That gets more true as more of the work is agentic.
3. We’ve got a lot of repos, and half of them haven’t been touched in a year or more. Can you see across all of that, or does this only work well on the code people are actively touching?
Flux analyzes the entire codebase. Foundation code and incoming changes both matter, and there’s significant value in watching the changes as they come in, because that’s where you catch trends before they become problems. A tool that only looks at the PR diff misses the other half of the picture: dormant code that’s been sitting there for years suddenly getting touched. That’s not automatically bad. It might mean someone’s finally paying down some overdue technical debt. But you do need to know it’s happening and be able to ask why, and a PR-only view can’t tell you that.
The same complexity that breaks ticket systems shows up here too. A code-based view gives you one consistent measure, built PR by PR from the bottom up, less exposed to human error and internal politics than a system built on what people remember to log.
4. We’re already shipping AI-generated code to production, and honestly we’re not sure our review process is catching what actually matters. Have you heard other teams worried about this?
You’re not alone. We hear about this constantly. Review looks different at every company and every stage, and it’s increasingly a mix of humans and tooling. The real worry is volume. As the pace and scale of change go up, the issues that slip through aren’t usually visible in one PR at all. They show up over time, across many changes, which is exactly the layer a single review gate can’t detect.
Determinism isn’t coming back
The report’s findings are a snapshot showing how engineering leaders and their teams are still working out how to deploy AI coding tools safely, and every organization is at a different point in that process. One thing isn’t up for debate: even using the same prompts and models won’t give you the same code twice. That’s just one reason why visibility into your changing codebase is essential going forward.
Check out the full webinar recording to learn more about our survey results and watch the discussion. Request a demo if you want to see Flux in action.